Showing posts with label MOCA. Show all posts

Thursday, January 3, 2019

Huge Trace Files - Not a problem!

Overview

JDA/RedPrarie has a very useful feature that allows for detailed tracing of a server component.  It provides information about every single server component, parameter, and also all SQLs that are executed.  But that also ends up being an issue as the traces would often reach several gigabytes.  Analyzing them becomes a problem.

Our Solution

Oracular (http://www.oracular.com) has created a client software that allows for executing MOCA commands.  It can be downloaded from http://autoupdate.oracular.com/mocaclient/ .  We have incorporated an advanced Trace Viewer into this application that allows for analyzing such trace files.  The concepts are based on some of the concepts described in my earlier blog.

Database Trace Option

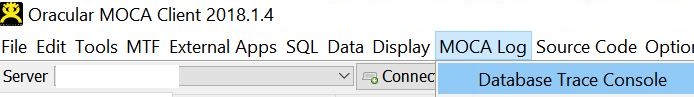
When you have our MOCA Client, you can access the "MOCA Log" pulldown menu:

As described in the earlier blog post, we will be pushing the trace to a set of tables in the database.  So in the screen you can press the button to create the tables on the instance.  This needs to be done only once.

Now you can choose the trace file you want to load from the instance by pressing the insert button.  There is no upper limit on the size of trace file.  You will be able to process several Gigabyte trace file and the client will give you progress update.  Once the trace file has been parsed the parsed view is stored in a set of database tables so re-analyzing it does not require re-parsing.

The parser views the trace file as having three high level perspectives:
  1. Activity.  This is from the point of view of a client that accessed a service provided by MOCA
  2. Commands.  These are the various MOCA commands
  3. SQLs.  These are the SQL statements that are executed

Activity View

As you select a trace file from the top grid, the various Activities will be displayed in the order of execution along with the time spent on each:

You may sort the grid as you see fit.  Each row here implies an interaction from the client (e.g. RF or GUI user) with the MOCA server.  Being able to view this is a huge benefit when trying to make sense of huge trace files as our interesting area may be one of several activities.  As you can notice that the client makes several calls to the MOCA server for house-keeping activities which create a lot of noise to filter through.  You can right click on any row here and export just that part of the trace file:

The exported trace file can be processed in any way you like, i.e. in a trace viewer of your choice.

Here you have two tabs "SQL" or "Commands" to do further analysis:


You can choose a tab and then press "Analysis" button.

SQL Analysis View

You can perform the analysis of the whole trace file or of a certain activity.  You decide that based on the filter section:

This shows a grid that has all SQLs within the context.  The SQLs here are the ones with bind variables.  This implies that we group like SQL statements.  This is extremely helpful when we are looking at a trace from the point of view of performance tuning:

You can sort the data as you see fit.  For example while looking for performance imporvements, sorting by tot_elapsed can be quite helpful.  There is also a summary section to separate the tracing overhead from the execution overhead.  The above example highlights that there is a single SQL statement that took 8 seconds.  But also that the seond one is executed very frequently and even though each execution was sub-second (0 ms to 101 ms) adding them together comes to 1.5 seconds which can be significant when looking at a transaction like inventory movement.

You can right click on any row here to see further options:
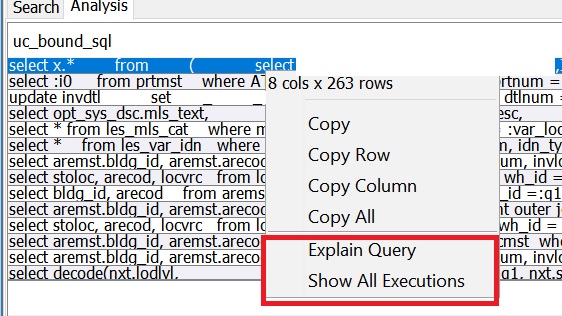
  • Show all executions will show each execution.  As you can see below it provides a summary view and also the time for each execution.  It also provides contextual information about the command that executed it and also the line number in the trace file.

  • Explain query will show an execution plan.  This is very useful as the explain plan is really dependent on the query with bind variables.  A common mistake is to analyze queries with bind variables replaced.  This provides a simple mechanism to get the trace


Command Analysis View

Like SQL Analysis, you can do command level analysis as well.  You can analyze the whole trace or focus on an activity.  Once you analyze you see similar output but from the point of view of MOCA commands:

You can see summary view and also similar statistics for the various commands within the analysis context.  You can for example focus in on a command that may be executed too often causing overall performance degredation.


Trace View Option

You also have the traditional option of viewing the trace file as a tree view or detailed view.  Here too we have several advantages over the competing options:
  • We can look at part of huge trace
As mentioned above when we right click on an activity we can create a trace for just that portion.  That sub-trace is opened into the trace viewer:


  • Ability to filter out noise
When we open a trace file, we get an option to filter out some typical parts of the trace to make it easier to view.
This will reduce the resulting view significantly as the common house keeping commands in MCS and MOCA will be ignored.  You can also put additional commands to ignore.  This also reduces the size by getting rid of some other parts of the trace.
  • Tree View and Detailed View in side by side panes
Above enhancements allows us to view very large trace files in this view as well.  Then we can see the contents in two panes where right side shows it as a tree and left side as text:

  • View Arguments in a tab
We can highlight a command in the tree view to see the arguments that are available to it in the Arguments tab:

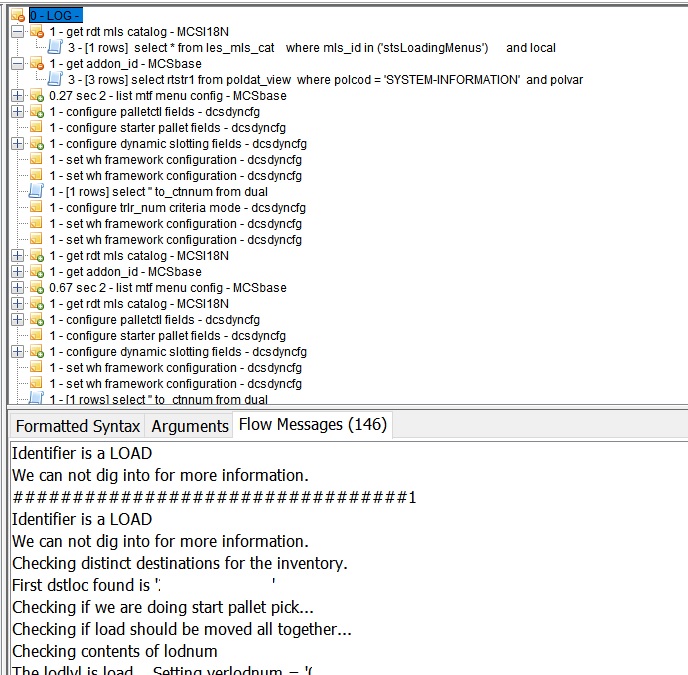
  • Easily see FLOW messages
MOCA code may put explicit trace messages as FLOW type.  These provide explicit trace hints that can be valuable in making sense of a complex command.  The "Flow Messages" tab shows such messages based on the selected node of the tree:
Conclusion

RedPrairie/JDA server tracing option is very valuable and provides a tool to perform indepth analysis and troubleshooting.  Complex use cases become difficult due to the size of the trace file.  Our approach provides us a solution to focus on the problems and eliminating noise.  Our consultants are also users of our tools so this allows us to imporve these by utilizing their feedback.  If you have any questions or comments please contact us.

Wednesday, September 12, 2018

RedPrairie/JDA Application Monitor

Overview

One thing that all large implementations have in common is the need for some tasks that need to be done periodically.  These may be tasks that are by design or due to some data corruption.  We often are unable to get the fix from the vendor or the fix may require an upgrade which may not be feasible.

In previous versions we had Schedule Agents that could do this.  In new versions we have a slightly more elaborate construct called jobs.  

Our Approach

At Oracular we employ a slightly more sophisticated approach to this problem.  We implement a concept of an application monitor that detects abnormalities and fixes them.  While it executes using the provided constructs of schedule agent or jobs - it provides a more abstract view of this problem and thus the overall solution is easier to manage.

We view the problem of an application monitor as follows:

  • Detect the issues of a certain type.  Return several rows where each row indicates the issue of this type.  This can take the form of a MOCA command or a SQL statement.
  • For each of the rows returned from above execute MOCA code to fix that situation.
  • Optionally log in dlytrn 
  • Optionally raise EMS alerts.
  • Provide a front-end so that advanced end users can manipulate these monitors or add new ones.
  • Run these as a single job so that overall job schedule is not adversely impacted.
  • Publish progress to the job monitoring framework developed by oracular

Our Solution

We define this monitors in a new table:
ColumnDescription
Monitor IdA unique name for each monitor
DescriptionDetailed information about it
Sort#To control the sequence in which the monitors run
Time Since Last RunSecond since last run. The monitor job could be running every minute but one of the monitors may be defined to run every 10 minutes.
Enabled?1/0 to enable it
Detect Command4000 byte field to provide MOCA or SQL to detect an abnormality. Return n rows.
Fix Command4000 byte field to provide MOCA to fix 1 row. Executes for each row returned from detect command
Log Dlytrn?1/0 to log dlytrn for each row returned by detect command
Raise EMS on Fail?1/0. if enabled, raise EMS alert if fix command fails
The solution is in the form of a single MOCA command called "run ossi monitor" that is scheduled using MOCA jobs.  We define this to execute every minute and to control individual jobs that we may want to run less frequently - we use "Time Since Last Run" concept.  Users can maintain this information themselves using a simple front-end application:


All WMS implementations have some of these jobs that are developed over time to handle typical issues.  For example:

  • We often have orphan invmov records.  We can detect such records and then delete them.
  • Sometimes we have pckmov records that do not have corresponding pckwrk records.  We can detect the condition and kill such pckmov records
  • It is common to have situations where rescod is not cleared.  We can detect the condition and run "deallocate resource location" for these locations.
  • It is often a requirement to reprocess downloads in EERR status.
  • We can create a monitor to detect some abnormal condition and send an email to a set of users with results of the query.  This solution is easier than creating an EMS alert since it does not require a rollout process and the email can include detailed results. 

Conclusion

Some sort of an application monitor is a common requirement in any large system and RedPrairie/JDA WMS is no exception.  Above design pattern can be implemented generally for any large system.  It looks at the problem abstractly and provides a solution that is simple to implement, maintain, and manage.  

Managing Long Running Jobs In RedPrairie/JDA

Overview

We often have jobs that perform long tasks.  There is no easy way to see the work they are performing at a given time.  The only option is to look at MOCA Console or other similar view which provides a very low level window into the MOCA command or SQL that is being executed.  Historical information is not easy to view either.

While this solution describes it in the context of RedPrairie/JDA - the concept is universal and can be used in any solution where long running operations are implemented.

Our Solution

At Oracular we have developed a universal approach to handle this problem which we apply in all of our solutions including RedPririe/JDA jobs.  We view any long running operation as follows:
  • Each instance of execution is a job
  • The job executes one or more modules
  • The module executes one or more actions
  • Start and stop of job, module, and action is recorded with timestamp in a separate commit context so that it is visible outside the transaction right way.
  • In case of an error the error information is recorded as well.
  • All of this information is kept in a database table so it can be referenced later
  • DDAs are available so that end users can view this information.
A table called usr_ossi_job_log records this information.  It has following structure:
ColumnDescription
Job#A new number for every job
Module#A new number for every module within the job
Action#A new number for every action within the module
WhoA string to identify user or other context which is executing the job
Job IdJob Name
Module IdModule Name
Action IdAction Name
Context DataAdditional Data
Started OnStart Date/Time
Ended OnEnd Date/Time
Error CodeIf an error occurs error code
Error MessageIf an error occurs error message

So as a job progresses it keeps updating this table in a separate commit context.  This allows the users to know exactly how far along this instance of the job is and given that we have historical data we can reasonably predict when the job will end.

Making It Happen!

To make it all come together we have created a set of MOCA commands and MOCA functions that allow our code to be simple and at the same time provide information to this table.  A typical such job will be structured as follows:
/*
 * Adds a row to the table with new job#, job-id, additional information, 
 * and who information.  The start date/time is logged as well.  module 
 * and action are set to % (literal).  Commits this data in a separate 
 * commit context
 */
publish data
where uc_ossi_job_seq = ossi__register_job ( 'JOB-ID, 'SOME-INFO', 
                        'WHO-INFO' )
|
try
{
    /* 
     * Some step(s) during the job
     * Adds row to the table for the job#.  gets a new module# and 
     * returns that.  Row has module name and also additional 
     * information as needed.  Additional.  Action is set to 
     * % (literal).  Additional Information can come in handy 
     * to for example to log when we are processing several 
     * rows of a domain, like processing orders in a wave.
     * You could log something like 1/n there so that you can see 
     * how far along the job is.  This is committed in a separate 
     * commit context.
     */
    publish data
    where uc_ossi_module_seq = ossi__register_module ( @uc_ossi_job_seq, 
                               'MODULE NAME', 'MORE DATA' )
    |
    try
    {
        /* 
         * This module will have 1 or more actions - each coded like
         * We do not have to use action concept - this becomes useful 
         * if we can divide a module further.  For example module could 
         * be an order and action could be pick.  Idea is same as module 
         * - here we can give action name and additional information
         * Additional Information can be used to provide specific 
         * details and also 1/n type of data.  This is committed in a 
         * separate commit context.
         */
        publish data 
        where uc_ossi_action_seq = ossi__register_action ( 
                                   @uc_ossi_job_seq, @uc_ossi_module_seq, 
                                   'ACTION NAME', 'MORE DATA' )
        |
        try
        {
            moca comamnds that do the work
        }
        finally
        {
            /*
             * uc_ossi_job_seq, uc_ossi_module_seq. uc_ossi_action_seq are in scope
             * so that row
             * is updated with timestamp and error information.
             * This is committed in a separate commit context.
             */
            complete ossi job log
            where uc_ossi_err_code  = @?
            and   uc_ossi_err_descr = @!
        }
    }
    finally
    {
        /*
         * uc_ossi_job_seq and uc_ossi_module_seq are in scope so that row
         * is updated with timestamp and error information.
         * This is committed in a separate commit context.
         */
        complete ossi job log
        where uc_ossi_err_code  = @?
        and   uc_ossi_err_descr = @!
    }
}
finally
{
    /*
     * Updates the row in the table for the job itself (added in 
     * register of job).  Sets end time and also error 
     * information if applicable.
     * This is committed in a separate commit context.
     */
    complete ossi job
    where uc_ossi_err_code  = @?
    and   uc_ossi_err_descr = @!
} 

So as this job progresses through several actions we will be publishing the progress of the job to this table - so we will know exactly how far along it is.  We will also know historically how long the job has taken and how long the various modules and actions have taken.

The data structure is generic and will work for any type of long running operation.

End User View

The users can view all of the jobs in a simple to use front-end.  First screen provides a dropdown to see all the jobs defined in the system:

Then it shows a view that indicates how many times the job has run and the times of the latest execution:
By going to the Job Log Detail Display, we can see the progress of the latest execution.  Here the users can see the progress of the currently executing job as well.
To see previous executions, go to Job Executions tab:

Summary

The users can view all of the jobs using this approach.   The data provided by this approach is extremely valuable for support.  We can detect if a job is stuck and also monitor progress of long running operations.  We can easily predict when the job will end and can objectively determine if the performance has deteriorated.  In case of performance we can pinpoint the exact operation that is the culprit.

Wednesday, September 5, 2018

RedPrairie/JDA RF Solution for the 21st Century

Overview

All Redprairie WMS implementations need an RF Solution - a solution for physical devices that are used on the floor to perform most of the warehouse functions.  Man Hours spent on these devices far exceed those on GUI screens.  But the solution for these devices looks the same as it did a decade ago.  Internally the infrastructure evolved to a Java based telnet emulation but from the point of view of an end user it has not improved much.

At Oracular we have been working with RedPrarie systems for a long time and we understand the pains and opportunities in such implementations.  Improving the RF Solution is part of that.

We have identified following areas as opportunities that we have addressed in our new solution.
  1. Connection Setup
  2. Touch Support
  3. Screen Layout
  4. Additional Information
  5. Voice Support

Solution Overview

Our solution is an Android app that is an evolution of our earlier solution.  While that solution was from the point of view of ad-hoc use - here our vision is to provide a solution for the warehouse floor.  As several customers are now choosing Android platform - the solution is a natural fit.

Whereas the standard RP solution is a thin telnet emulation - our solution builds on top of that.  All of the delivered and custom RF screens would work without any tweaks - but at the same time the solution can be enhanced by providing additional contextual information to the user.

In order to make it happen, our solution makes a direct connection to the MOCA server so that it can access it and also keeps a telnet window open.  It also utilizes advanced screen scrapping and keyboard manipulation to streamline the data management.

Salient Features

Following is a list of some key features that we have incorporated in our solution.

Connection Setup

A typical warehouse may have hundreds of these devices and the typical users are not technically savvy.  So maintaining these becomes a chore.  Each device needs to have some setup done for following reasons:
  • Define environments that it can connect to.
  • Identify it individually to the application so that DEVCOD variable is set properly
Environment management can become a major headache for system administrators.  Updating the information on several devices is time consuming.  Using the same device against multiple environments or re-purposing a device is not straight forward either.

Our solution solves this problem by defining a single URL for all connection details which will remain the same for all devices.  All of the changes are then done on that single location.

Profile
First we have a concept of profiles.  These are maintained by a simple XML file and these point to the various MOCA environments that the devices may connect to:
<ossi_rf_emul_profiles>
<profile name="env_1">
<app_url>http://10.10.10.10:8110/service</app_url>
<prompt_user_id_first>1</prompt_user_id_first>
<short_name>AC</short_name>
</profile>
<profile name="env_2">
<app_url>http://10.10.10.20:8110/service</app_url>
<prompt_user_id_first>1</prompt_user_id_first>
<short_name>AD</short_name>
</profile>
</ossi_rf_emul_profiles>
This defines following:
XML TagValueComments
nameArbitrary ValueProvide a name of this environment
app_urlMOCA URLURL that connects to this environment
short_nameArbitrary ValueAbbreviated name of the environment to show on the emulator
prompt_user_id_first0 or 1Ask for username and password after connection

Profile_dtl
In the same location, we will have profile detail XML files for each of the profiles defined above.  The XML file is named profile_dtl_name.xml.  For example:
<ossi_rf_emul_profile>
<setup name="env1">
<mtf_url>10.10.10.10:8112</mtf_url>
<short_name>AC</short_name>
<wh_id>WMD1</wh_id>
</setup>
</ossi_rf_emul_profile>
This defines following:
XML TagValueComments
nameArbitrary ValueProvide a name of this environment
mtf_urlMTF URLHost and port of the MTF telnet connection
short_nameArbitrary ValueAbbreviated name of the environment to show on the emulator
wh_idWarehouseAs defined in wh table


When our emulator starts, user selects the appropriate profile and then profile detail.  With this input we know the application URL, MTF URL, and  warehouse Id.  The application will then prompt for username and password for the application URL.  This will allow the emulator to directly connect to the MOCA server and at the same time open a telnet connection to the MTF server.

Device Identification
In order to identify each physical device to the application server RedPrairie has used various techniques over time including:
  • Requiring fixed IP addresses and using last three digits
  • Utilizing "answer back" and then responding with a value from the device.
Both can work but are not easy to setup.  Fixed IP addresses are not suitable at all these days.  Answer back works but requires per-device configuration.

Our solution in this case is to support these legacy concepts and extend it further to make things simpler.  Each physical device provides several interesting identifiers that can be utilized for example:
  • IP Address (if fixed IP address)
  • Bluetooth Id
  • MAC Address
  • Serial Number
MAC Addresses and serial numbers are especially interesting since they are often known from the product packaging and are already set.  In RedPrairie we already have a concept of defining each device as "RF Terminal" using "RF Terminal Maintenance"

As you can see here rather that utilizing "answer back" we define one of the following attributes for each device - and while defining we can use wild cards:
  • IP Address
  • Bluetooth Id
  • Mac Address
  • Serial Number
So in our solution when the "RF Terminal Id" prompt shows up on the emulator, we automatically key in the corresponding terminal id.


Touch Support

Some hardware devices are quite compact where keys are quite small and typing can be tricky.  Our emulator provides touch support.  This comes in handy for situations like:
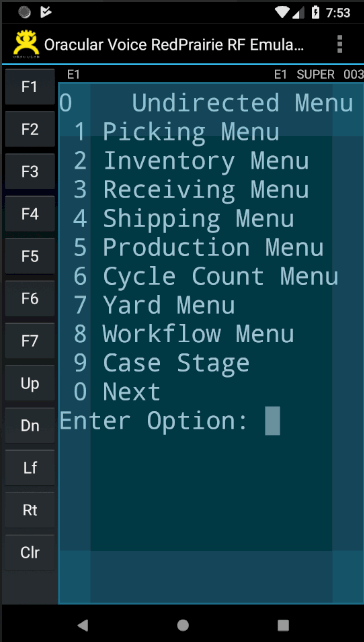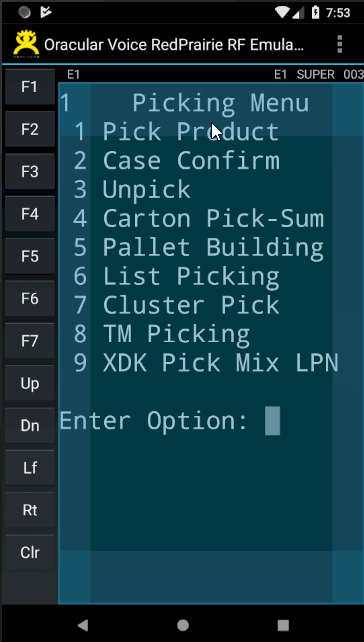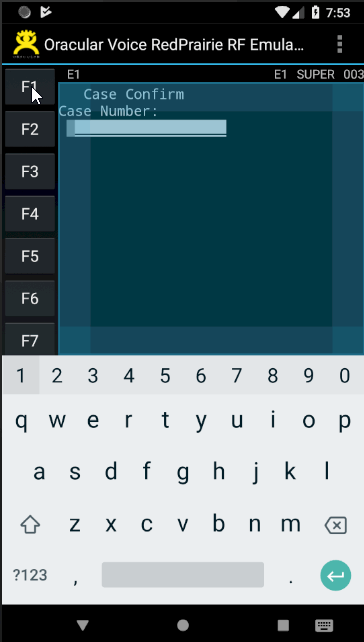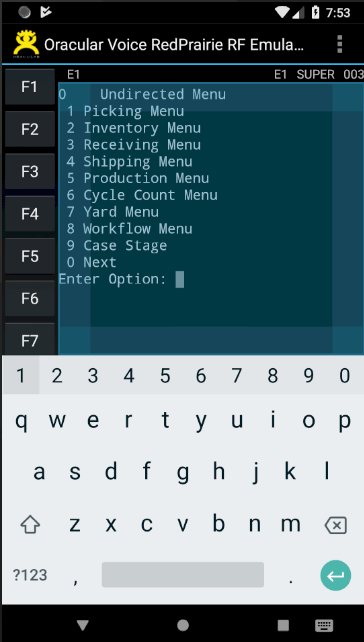
  • Selecting menu options
  • "Pressing" Function keys

Screen Layout Enhancements

15 years ago defining an RF screen in terms of lines and columns of characters made sense but today these devices have high resolution screens - so in reality a lot of usable real estate is wasted.  Our solution maximizes the real-estate in several ways:
  • Function Key pallet is displayed on left side - making it easier to manipulate them.  Refer to the images displayed above to see the function key pallet.
  • Soft Keyboard support.  Refer to the image above to see how the soft keyboard appears and disappears
  • Automatically Zoom In and Zoom Out to maximize the use of real-estate.  Refer to the image above to see how screen automatically zooms in and out based on the soft keyboard
  • Top of the screen provides connection details like environment, user, etc.

  • Bottom section of the screen can provide additional contextually sensitive information (described below)

Additional Information

RedPrairie standard RF screens often need to be complimented with additional information.  They do not provide simple ways of providing that so sometimes users would switch to alternate front end with GUI, or have reports.  Our approach in this case is to utilize the full capabilities of the devices and allow users to extend the view with additional information based on the context.  For instance if a pick directs you to a location we could show the inventory in the location along with its attributes like lot, and origin.  We can show multiple pages and the information provided can be different for different users.  The information could be from external sources as well, e.g. ERP or external websites.

This is defined by users themselves and is not a development task.

LES Command Maintenance
We use the les_cmd table to store the commands that are used for this purpose.  This allows us to make changes without needing "mbuild" and thus avoid rollout requirements.  When we execute these commands we always execute the highest level commands - thus providing a mechanism for overriding them as well.

If we want to show a URL then the command returns a special variable called "url":


We have two types of commands - the ones that show data (as shown above) and others that detect the context.  These commands always return one row and one column with a value of 1 or 0:

Additional Information Definition
Additional RF Form Information is defined as a collection.  Several pages may be defined in one collection.  The collection also describes how it fetches the context from the RF form that is running.  The screenshot below indicates that "wrkref" is scrapped from the screen to establish context.  Then three pages will be displayed below the form for additional information.  Each "page" has associated command which would return the data.


Setups
We have defined the various page groupings above.  To use them in a specific context we use the concept of "setups".  Several setups can be defined for an RF form.  Each setup has an associated "condition command" and "Additional Information Id".  The first setup where the conditional command returns true will be used.  This concept can be used to display different types of additional information on same RF form.  For example we could show different data based on type of user or other context information.  A supervisor could, for example, see the inventory levels in the system while doing counting but other users will not.


How it all comes together
When a user goes into an RF form, we check if this form has a setup which is active based on the pre-condition defined.  If there is one we then find the various pages and the associated commands.  We utilize the bottom section of the RF form to show this data where various pages are displayed as tabs and data is displayed in a grid.

Voice Support

If devices support voice, the RF emulator can utilize it as well.  It can speak the form name and the field name.


Conclusion

We have been working with RedPrairie WMS for a long time and understand the intricacies of the architecture.  We also understand the deployment framework and use cases.  This allows us to appreciate the gaps and this solution is based on years of experience in deploying these solutions in various industries and environments.   Once deployed users will appreciate the new capabilities which will result in ease of use and improvement in quality and throughput.  The system support will also become easier.

If you want additional information about this solution or any other Oracular solutions or initiatives contact me at saad.ahmad@oracular.com.  Visit us at http://www.oracular.com